




In the rapidly evolving landscape of AI-driven search, a quiet transformation is occurring within the "black box" of Large Language Models (LLMs). For years, industry analysts and SEO professionals have operated under the assumption that ChatGPT’s search capabilities were essentially a mirror of Bing’s index. However, recent empirical data—culled directly from traffic logs and technical teardowns—suggests that the reality is far more nuanced. ChatGPT is no longer a passive passenger to Bing; it is an active, selective curator of information, particularly when it comes to Reddit.
Main Facts: A Selective Curator
The prevailing narrative that Reddit has been "shadow-banned" or sidelined by AI search engines is being challenged by new evidence. Detailed traffic analysis shows that when ChatGPT processes complex queries, it doesn’t just scan the open web; it executes highly specific, targeted searches.
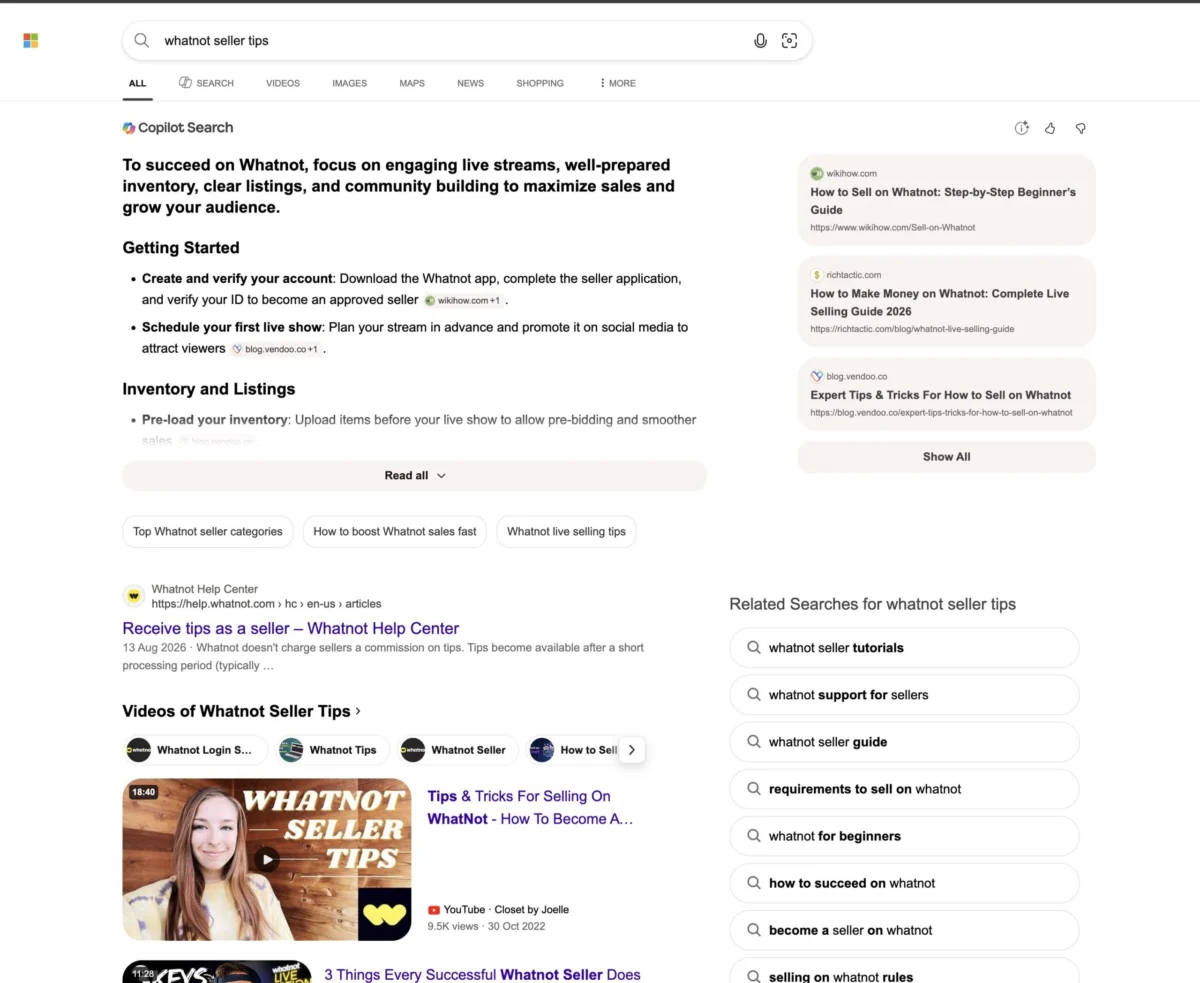
In a recent experiment, researchers observed the model autonomously generating a search string for "whatnot seller tips." Instead of a generic broad search, the model specifically targeted site:reddit.com/r/whatnotapp with a 3,650-day window—a decade of community-sourced wisdom. The result? Reddit accounted for 68% of all retrieved data, and notably, it became the primary source of citations in the final answer.

This indicates that ChatGPT is not moving away from Reddit as a source of truth. Rather, it has moved to a sophisticated "query-dependent" model. When the query requires practical, experiential knowledge—such as niche seller tips—the model aggressively pulls from Reddit. When the query involves commercial vendor categories, such as "best ai live chat support software," Reddit is often bypassed entirely in favor of commercial documentation and comparison sites.
Chronology of the Investigation
The discourse surrounding Reddit’s presence in AI search has moved through several distinct phases over the past few weeks:
- Mid-August 2026: Initial reports emerge suggesting that Reddit citations in ChatGPT have plummeted. Industry observers noted that while the model still "read" Reddit data, it rarely credited the source.
- August 21, 2026: A foundational teardown is published, documenting how ChatGPT fetches Reddit content at the domain level but fails to attribute it, leading to the theory that Reddit was becoming an "invisible input"—feeding the model’s intelligence while vendor pages collected the credit.
- August 24, 2026: A follow-up experiment is conducted using the "whatnot seller tips" query. This capture provides the "smoking gun" that contradicts the "invisible input" theory: the model does cite Reddit, but only when the query context deems it the most authoritative source.
- Late August 2026: Technical analysis of robots.txt and user-agent behavior confirms that OpenAI is treating its own agents differently than standard crawlers, indicating that the licensing deal between Reddit and OpenAI is likely facilitating data access that remains hidden from standard public search crawlers.
Supporting Data: The Disparity in Fetching vs. Crediting
To understand why the industry is divided on this issue, one must look at the quantitative data. In side-by-side tests conducted by technical analysts, the behavior of the model varies wildly based on the intent of the user.

| Query | Pages Fetched | From Reddit | Citations | "Won" by Reddit |
|---|---|---|---|---|
| Whatnot seller tips | 71 | 48 | 8 | 6 |
| Best AI live chat software | 221 | 84 | 11 | 0 |
The data proves that the model is perfectly capable of retrieving Reddit threads for both queries. The disparity lies in the decision-making layer. For the "live chat" query, the model fetched 84 threads but gave them zero citations. This suggests that for commercial, vendor-heavy queries, the model prioritizes "official" documentation—likely as a guardrail against hallucination or to favor high-authority commercial partners. Conversely, for community-driven queries, Reddit is treated as the gold standard.
The Bing Factor
A significant breakthrough in this investigation was the decoupling of ChatGPT from Bing’s index. Ryan Jones, a prominent analyst, demonstrated that Bing’s own SERP (Search Engine Results Page) is often entirely devoid of Reddit for commercial queries. While many assumed ChatGPT was merely "re-ranking" Bing results, the data shows that ChatGPT’s retrieval pool is significantly different from Bing’s. Whether OpenAI is utilizing its own proprietary index or a direct, real-time feed from the Reddit partnership remains the subject of intense speculation.
Official Responses and Technical Barriers
The question of "access" has been central to this debate. Jenny Halasz, among others, raised concerns regarding whether Reddit’s robots.txt files were blocking AI agents.

Technical testing confirms that the situation is complex:
- User-Agent Differentiation: Reddit serves different responses based on the user agent.
GPTBotandChatGPT-Userfrequently receive 403 (Forbidden) errors, whileOAI-SearchBotreceives a 200 (OK) response. - Geographic and Technical Masking: Testing from various residential and data-center IPs reveals that Reddit’s gatekeeping is not merely based on user-agent strings but on complex IP verification against known crawler ranges.
- The Licensing Reality: It is critical to distinguish between crawling and licensing. Because OpenAI has a formal data-sharing agreement with Reddit, the model likely accesses content through an API feed, rendering the limitations of robots.txt and traditional "crawling" partially irrelevant.
Implications for the Industry
The implications of this shift are profound for both content creators and SEO professionals.
1. The End of the "One-Size-Fits-All" SEO Strategy
We can no longer assume that optimizing for "Search" means optimizing for a uniform index. The AI’s decision to favor Reddit for community-led content means that brand-owned forums and community pages are now in direct competition with Reddit for "experiential" search traffic. If a business wants to be cited by an AI, it must prove its authority as a community hub, not just a vendor.

2. The Influence of Uncited Data
Perhaps the most unsettling finding is the "influence without attribution." When ChatGPT fetches 84 threads and cites zero, it is still using that data to synthesize an answer. For content creators, this creates a "black hole" where their intellectual property is used to train or inform the model, yet they receive no traffic or brand recognition in return. This "invisible input" model may become the standard for commercial queries, where the AI prioritizes efficiency and consensus over source transparency.
3. The Future of AI Search Transparency
The experiment highlights that we are entering an era of "Contextual Search." Future SEO strategies will need to account for the AI’s intent-classification layer. Content creators must determine whether their material is categorized by the AI as "experiential/community" or "commercial/definitive."
Conclusion
The "Reddit Citation Drop" is not a systemic failure of the AI’s ability to access the platform; it is a feature of a maturing, hyper-selective retrieval system. ChatGPT is learning to identify when the wisdom of the crowd is superior to the marketing copy of a vendor.

While the industry continues to debate the ethics of "invisible inputs" and the technical nuances of robots.txt, the data is clear: Reddit remains a vital component of the AI’s knowledge base. The challenge for the future is not how to get the AI to "see" Reddit, but how to ensure that the creators behind that content receive the visibility they deserve when their insights are used to construct the answers of the future. The door to Reddit is open, but the AI is now the one deciding who gets to walk through it.
