



For the modern knowledge worker, the rhythmic ping of a Jira notification or the collaborative hum of a Confluence page is the heartbeat of the workday. On Thursday afternoon, that heart skipped a beat, leaving thousands of Australian teams—and their global counterparts—in a state of forced, albeit temporary, productivity limbo.
As Atlassian’s suite of mission-critical tools faltered, the sudden silence across project management boards and documentation wikis triggered a familiar digital phenomenon: a collective sigh of relief among tech workers, swiftly followed by a wave of irony-laden humor on social media. While the outage was relatively short-lived, it served as a poignant reminder of the fragility of the digital infrastructure that underpins the global knowledge economy.
The Chronology of the Disruption
The incident began in the early afternoon, catching many teams at the peak of their post-lunch productivity. According to official logs from Atlassian, the first signs of instability emerged at approximately 2:22 pm AEST.
The impact was swift and widespread. Users attempting to access Jira Cloud, Jira Service Management, and Confluence were met with gateway errors, infinite loading screens, and intermittent timeouts. For organisations heavily integrated with the Atlassian ecosystem, the disruption was not merely an inconvenience; it was a total halt to operations. Sprint planning meetings were paused, customer support tickets sat in a state of suspended animation, and the "single source of truth" for thousands of projects vanished behind a wall of server-side errors.
Atlassian’s status page, usually the first port of call for frustrated administrators, quickly updated to reflect the severity of the situation. As the afternoon progressed, the company confirmed that its engineering teams had identified the root cause of the instability. By 3:16 pm AEST, less than an hour after the initial reports, Atlassian declared the incident resolved.
"Services are now operating normally for all affected customers," the company stated in its final update. While the disruption lasted less than an hour, the fallout in productivity and the subsequent "outage humor" on platforms like X (formerly Twitter) and LinkedIn highlighted just how deep Atlassian’s tools are embedded in the day-to-day lives of developers, project managers, and content creators.
Anatomy of the Outage: Why Atlassian Matters
To understand the frustration of Thursday’s outage, one must look at the ubiquity of the Atlassian product suite. Jira has become the industry standard for agile project management, acting as the primary dashboard for software development lifecycles (SDLC) across the globe. Confluence, meanwhile, serves as the "brain" for many enterprises, housing everything from technical documentation and product requirements to HR policies and strategic roadmaps.
When these systems go dark, the impact is systemic. For a software development team, a Jira outage means no visibility into bug tracking or feature development. For a customer support team, a Jira Service Management outage means an inability to triage incoming requests or update clients on existing tickets. The resulting "down time" is a paradoxical experience for tech workers: they are effectively "freed" from their tickets, yet unable to perform the core functions of their roles.
The Human Element: When the Tools Go Quiet
Perhaps the most interesting aspect of Thursday’s incident was the immediate reaction from the workforce. As the realization set in that the issue was systemic and out of their control, the tech community did what it does best: it turned to humor.
On social media, the #AtlassianOutage hashtag quickly became a repository for memes and jokes. One user remarked, "The Jira outage is the closest thing to a vacation I’ve had all year," while others joked about the sudden "forced off-site" or the rare joy of a status meeting that could not be held because the agenda document was inaccessible.
However, beneath the humor lies a serious anxiety. As companies move further toward cloud-first, SaaS-dependent models, the "single point of failure" risk becomes increasingly pronounced. Thursday’s outage was a reminder that even the most robust platforms are subject to the laws of digital entropy.
Official Responses and the Road to Transparency
Atlassian has remained characteristically disciplined in its communications regarding the incident. The company did not immediately offer a specific technical cause for the failure, opting instead to focus on resolution and service restoration.
In a statement released shortly after the resolution, the company committed to a standard of transparency that is expected of a market-leading enterprise software provider. "A public postmortem for this incident will be made available on this page when our full investigation of the incident has been completed," the company stated.
This commitment to a "public postmortem" is a vital part of the trust-based economy that SaaS companies occupy. For enterprise customers—some of whom pay millions annually for these tools—the "why" is just as important as the "how." Was it a misconfigured deployment? A database bottleneck? A cascading failure triggered by a third-party service? The engineering community will be watching the upcoming postmortem closely, as it will likely contain lessons on resilience and redundancy that are applicable across the industry.
Implications for the Future of Work
The 2026 Atlassian incident, while minor in the grand scheme of historical IT outages, raises broader questions about the reliance on centralized platforms. As organizations scale, the "all-eggs-in-one-basket" approach to productivity software creates a concentration of risk.
1. The Resilience Mandate
For IT leaders, the event serves as a call to review their business continuity and disaster recovery (BCDR) plans. How do teams operate when their primary management tool goes offline? Does the organization have offline-capable documentation? Are there manual fallbacks for mission-critical tasks?
2. The SaaS Dependency Trap
While the shift to the cloud has undoubtedly accelerated innovation and allowed for better collaboration across distributed teams, it has also ceded control to the vendor. When a vendor’s cloud architecture experiences a hiccup, the customer is effectively locked out of their own data. This tension is likely to drive further interest in hybrid-cloud configurations or decentralized project management alternatives, though the network effects of Atlassian’s ecosystem make switching costs prohibitively high.
3. The Productivity Paradox
The "freedom" felt by workers during the outage is a double-edged sword. It highlights a culture of constant connectivity and ticket-driven productivity that can lead to burnout. Organizations might consider the outage a "forced experiment" in whether these tools are being used optimally, or if they are simply creating a layer of administrative friction that occasionally paralyzes the very work they are intended to facilitate.
A Broader Context: Tech Industry Turbulence
It is worth noting that this incident occurred in a week already marked by broader concerns regarding the stability of cloud services. In the current economic climate, where "doing more with less" is the prevailing mandate for tech firms, the strain on engineering teams to keep legacy systems running while pushing for rapid innovation is immense.
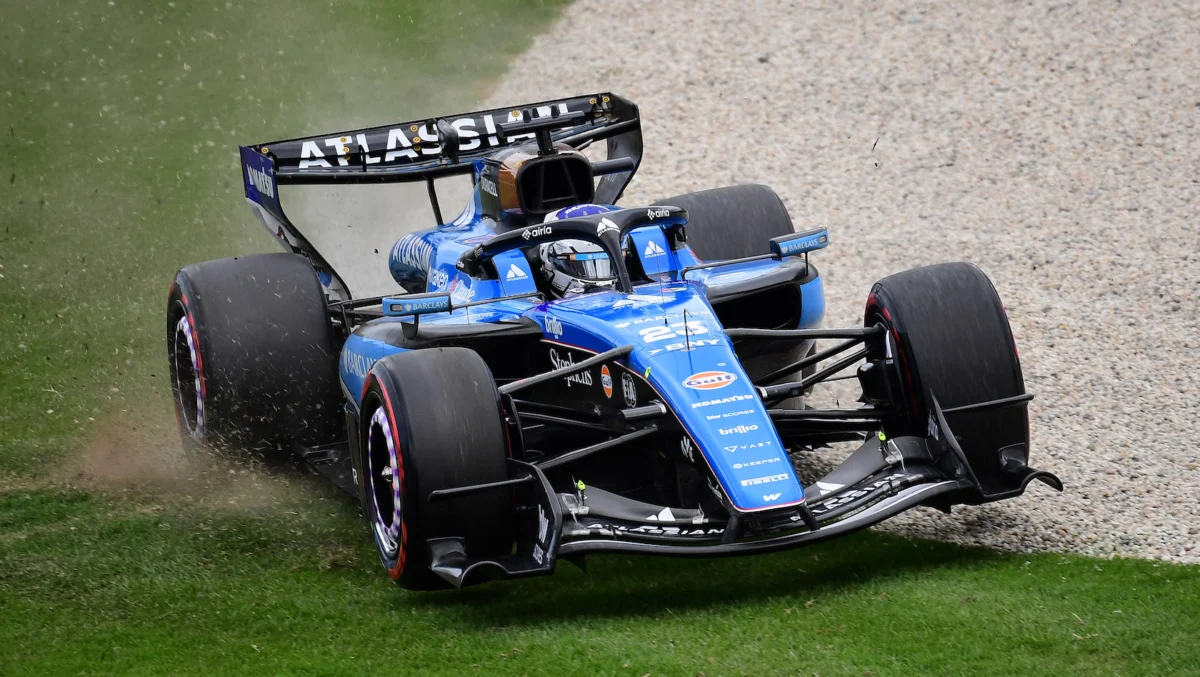
The image of the Atlassian-sponsored Williams Racing F1 car—provided as a visual reminder of the company’s high-octane branding—stands in stark contrast to the quiet, behind-the-scenes engineering work required to keep these platforms stable. Like a pit crew for a global team, Atlassian’s infrastructure engineers are often invisible until something goes wrong. When a car spins out on the track, the crowd notices; when a server goes down, the entire global office notices.
Conclusion
The outage of Thursday, while brief, acted as a mirror for the modern workplace. It reflected our deep-seated reliance on digital infrastructure, our tendency to find humor in the face of technical frustration, and our demand for transparency from the giants that manage our data.
As Atlassian prepares its postmortem, the company—and its millions of users—will be looking for answers. Was this a unique fluke, or a symptom of the growing complexity of large-scale cloud ecosystems? Regardless of the findings, the incident serves as a timely reminder that in the world of high-tech project management, even the most finely-tuned engines need a pit stop every now and then. For now, the tickets are flowing again, the dashboards are illuminated, and the world of work returns to its familiar, albeit slightly more cautious, rhythm.
